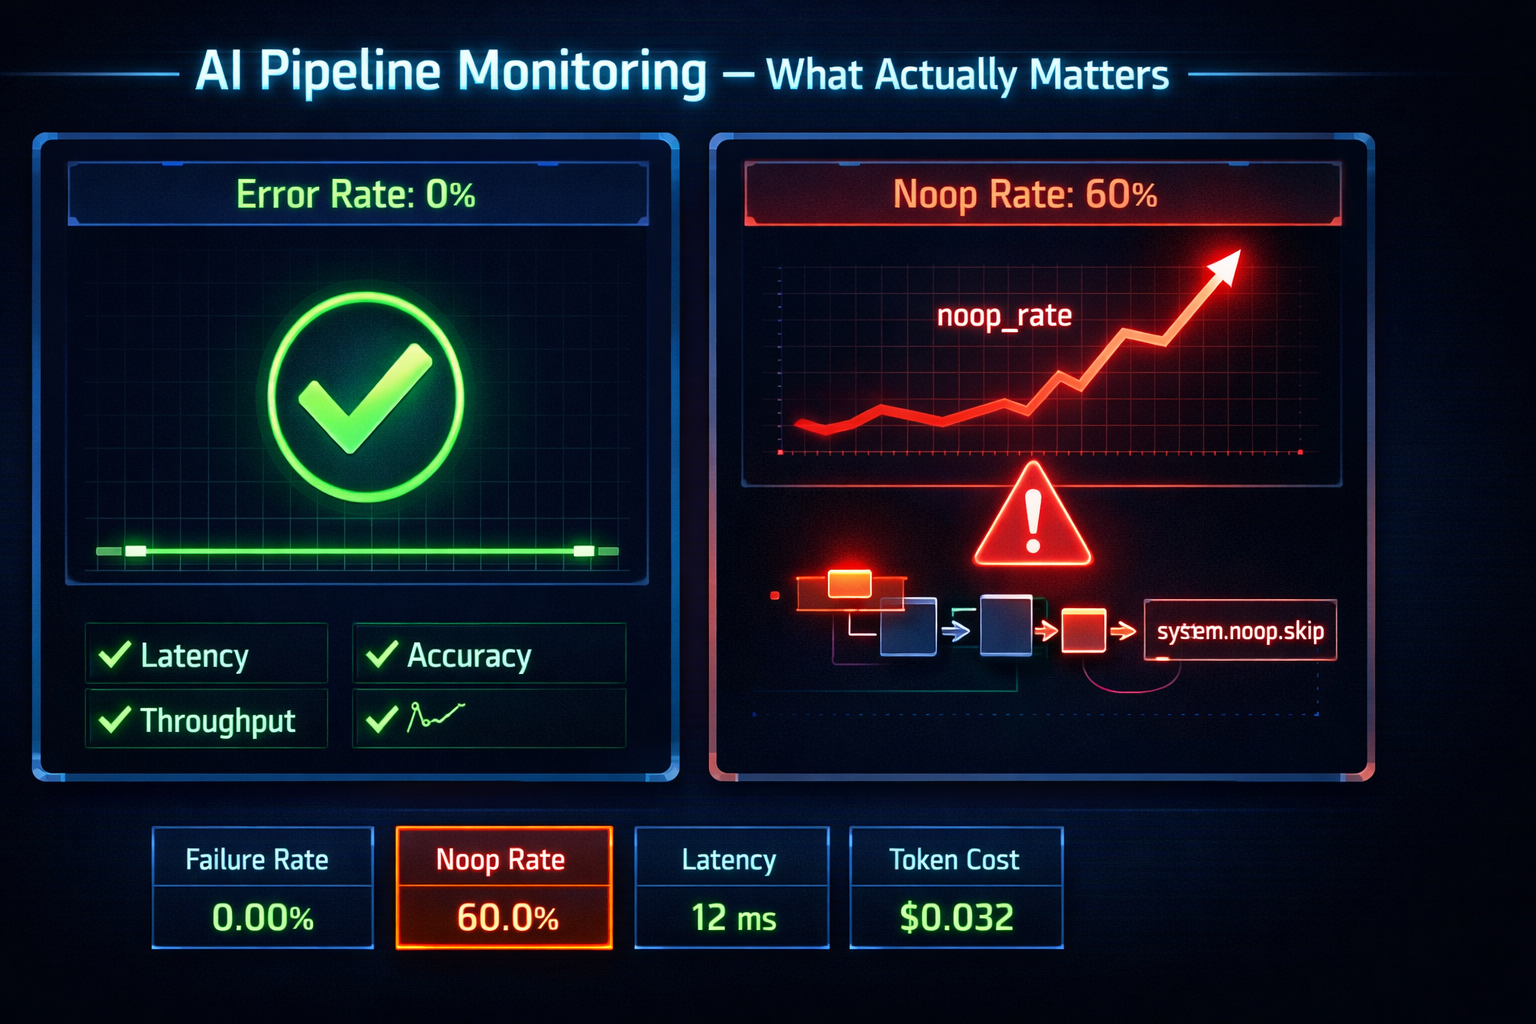
Your Error Rate Is Zero. Your AI Pipeline Is Broken.
Traditional monitoring misses the most dangerous AI failures. Here are the four metrics that actually matter — and the one most teams never track.
Technical deep-dives on AI pipelines, WhatsApp automation, and the architecture behind WhatsRB Cloud.

Traditional monitoring misses the most dangerous AI failures. Here are the four metrics that actually matter — and the one most teams never track.

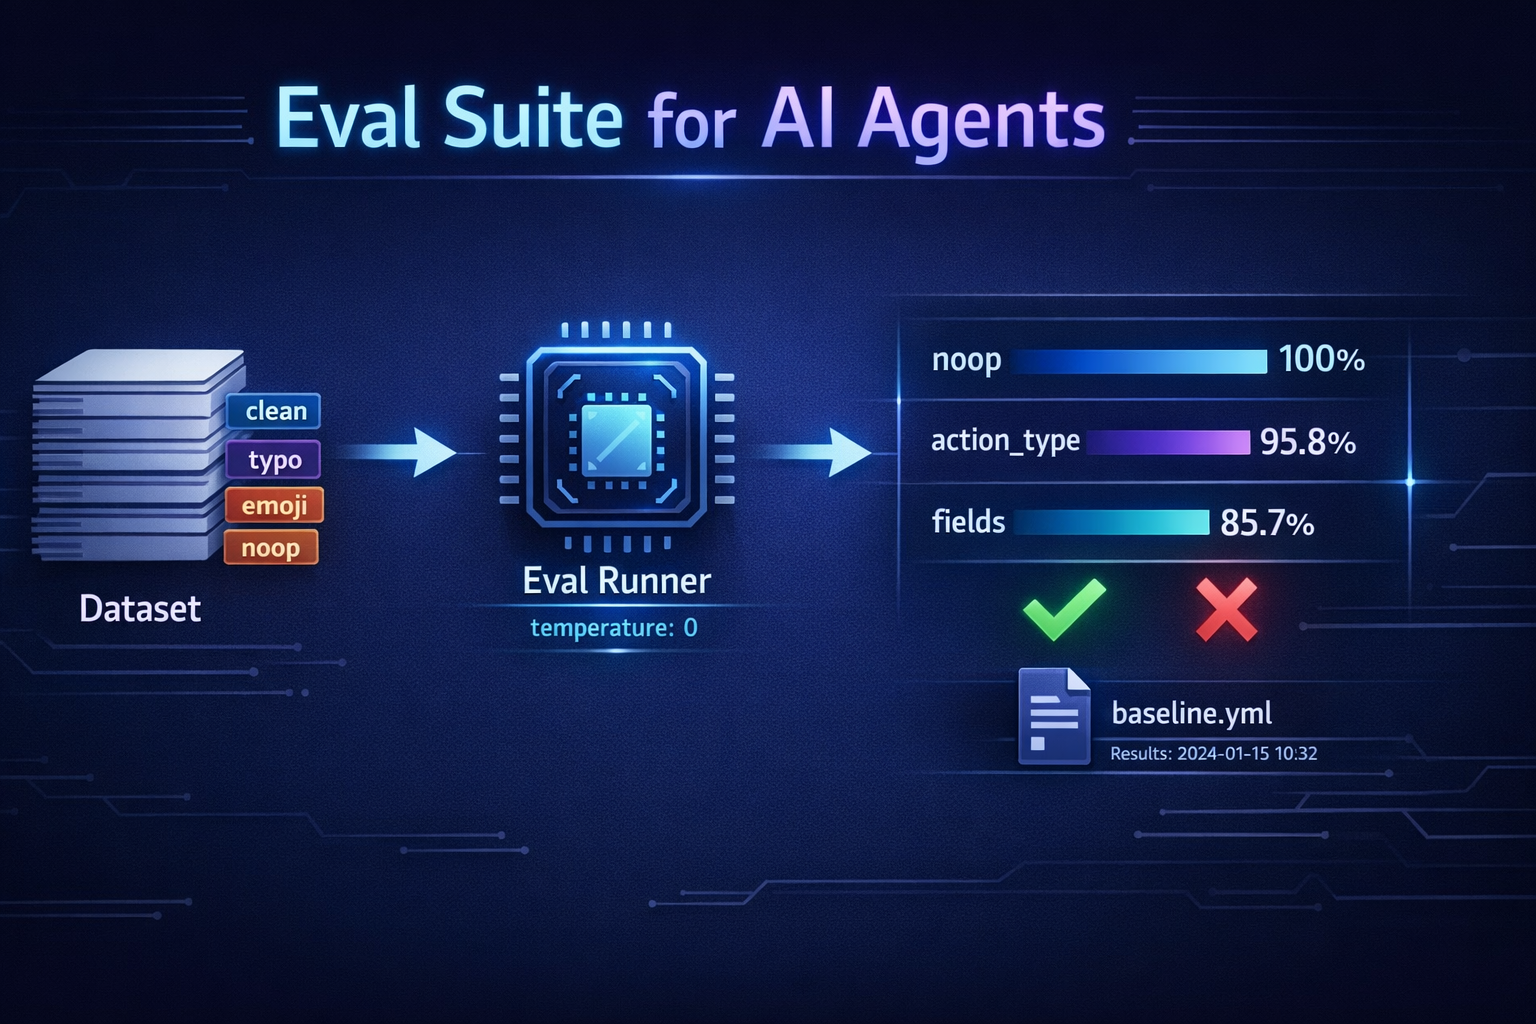
You can't assert on LLM outputs the way you assert on functions. Here's how to build an eval suite that catches regressions, tracks accuracy over time, and costs less than a coffee.

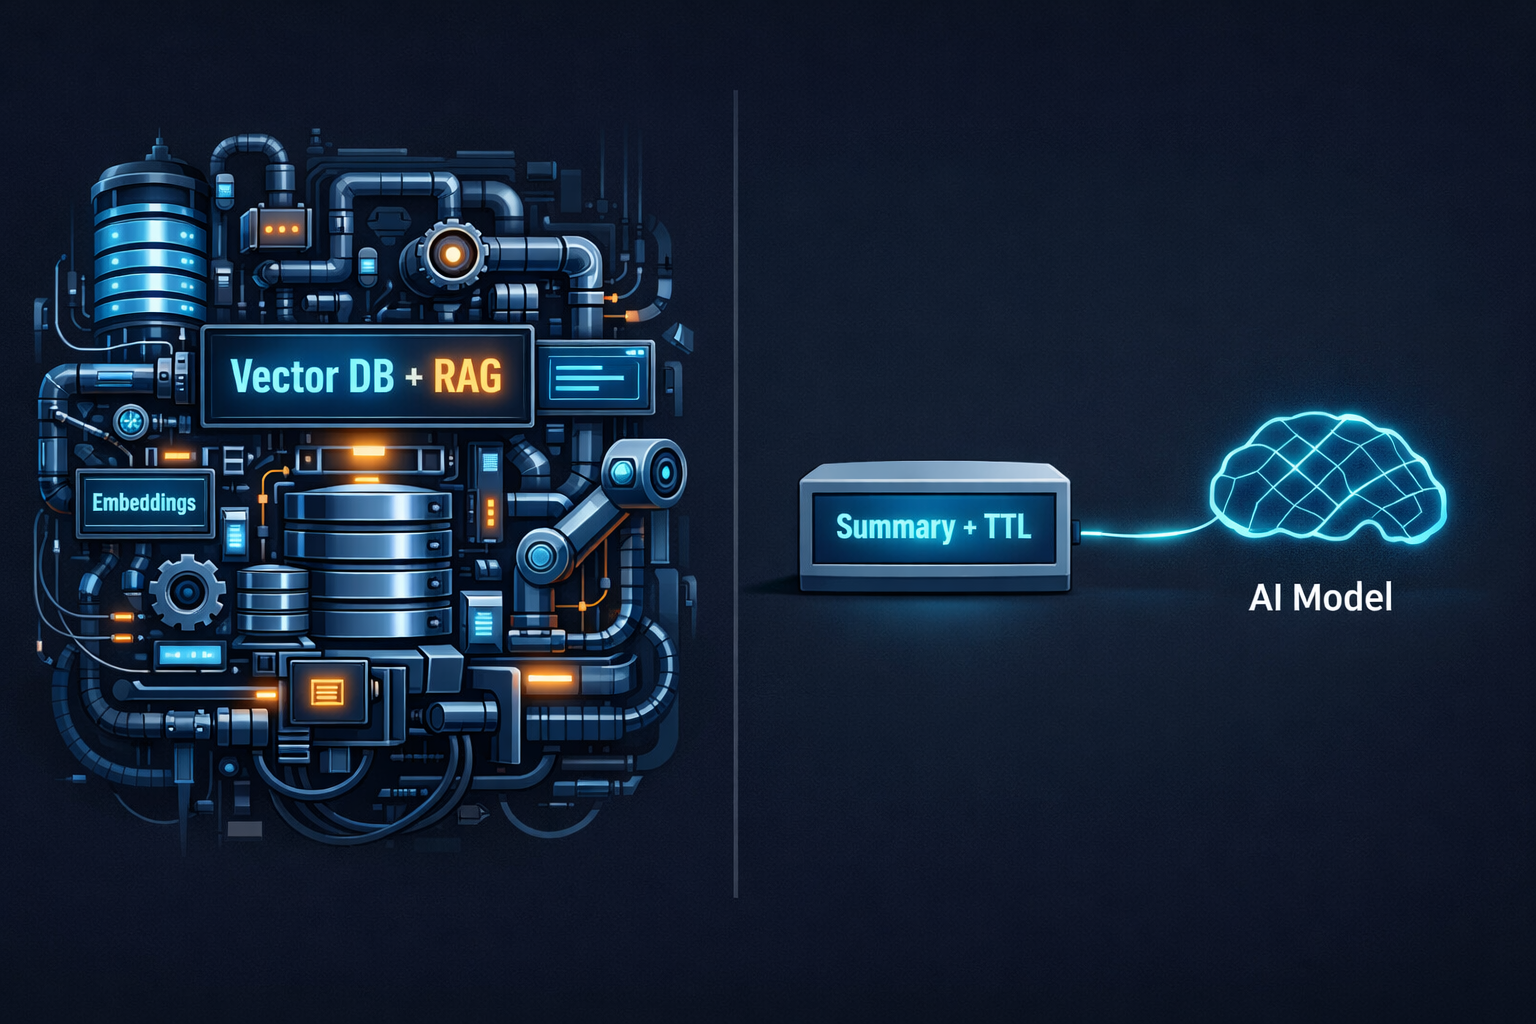
Most AI context solutions are overengineered. For short-lived conversations, a one-line summary and a TTL is all you need. Here's the pattern.

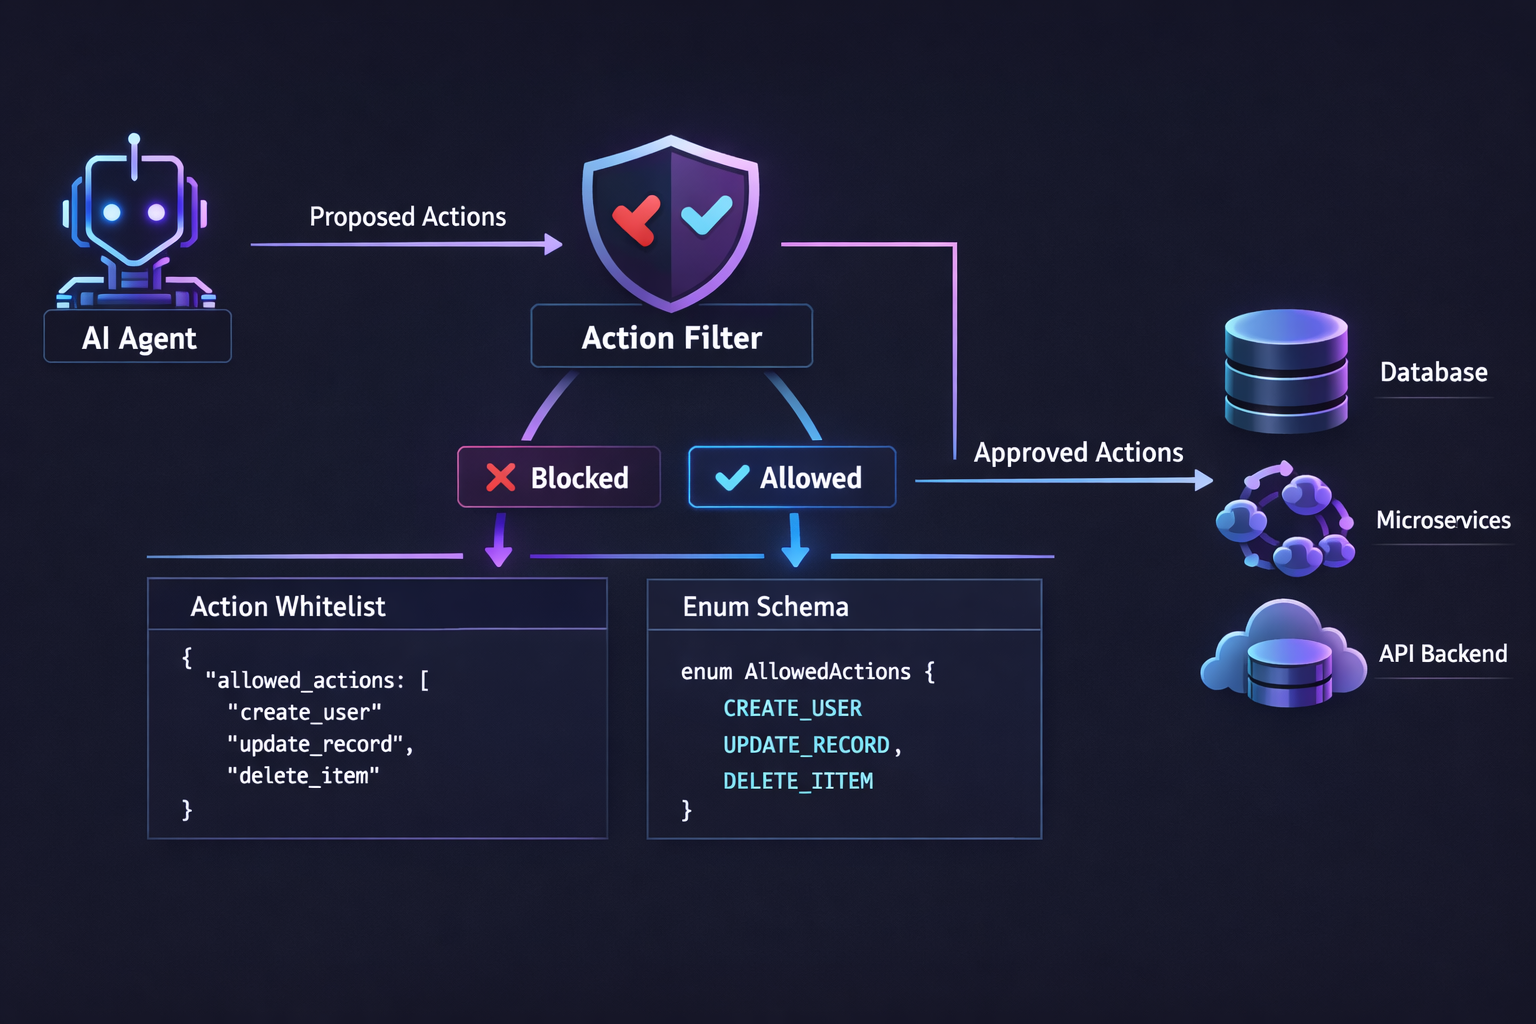
Free-form AI agents invent actions your backend can't handle. The fix: a strict allow-list injected into the LLM's tool schema. Here's the pattern.

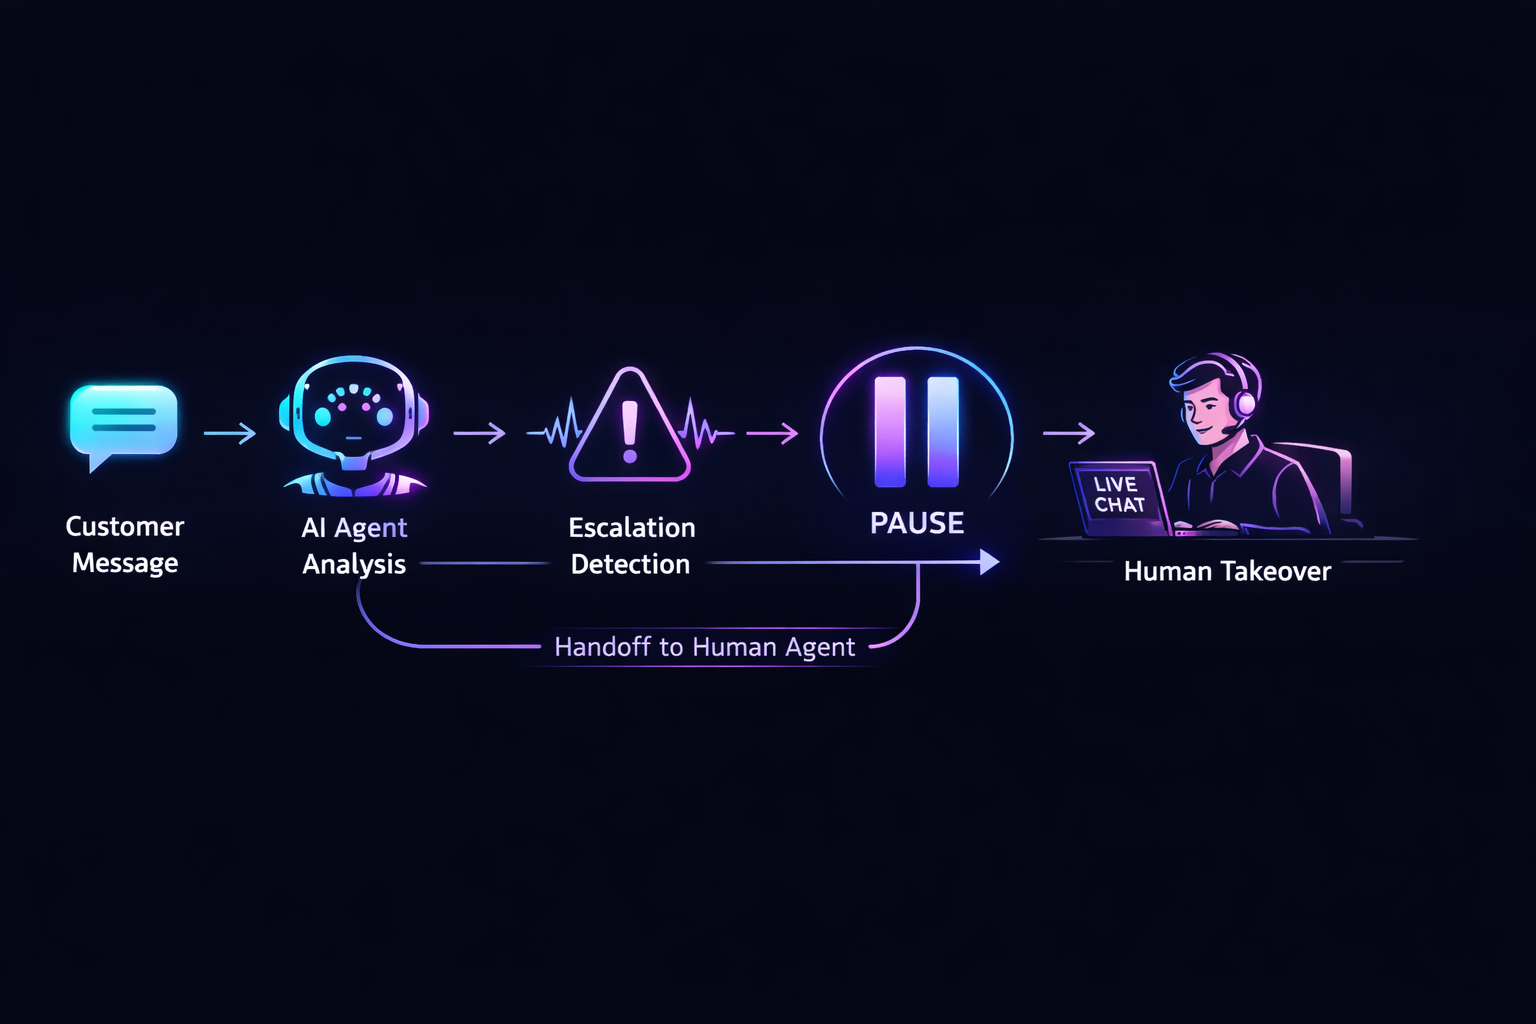
Three triggers, automatic expiration, cached hot-path checks — the complete pattern for AI-to-human handoff in messaging systems.

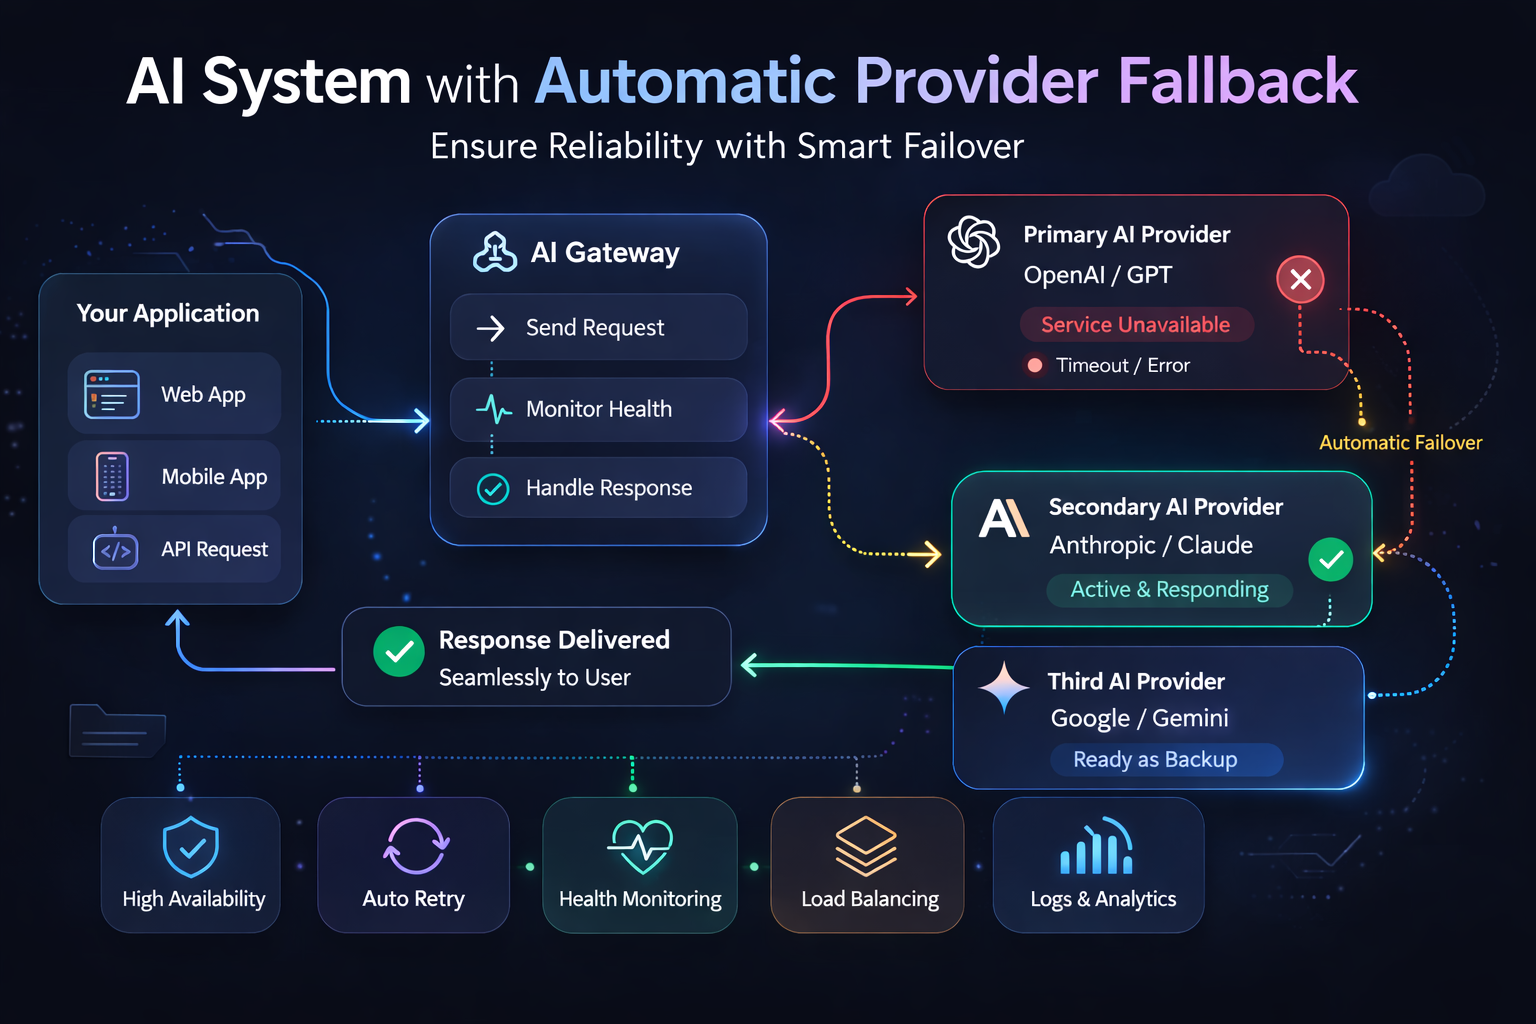
Your AI provider will go down. The fix is dead simple: an adapter pattern with automatic fallback to a different provider.

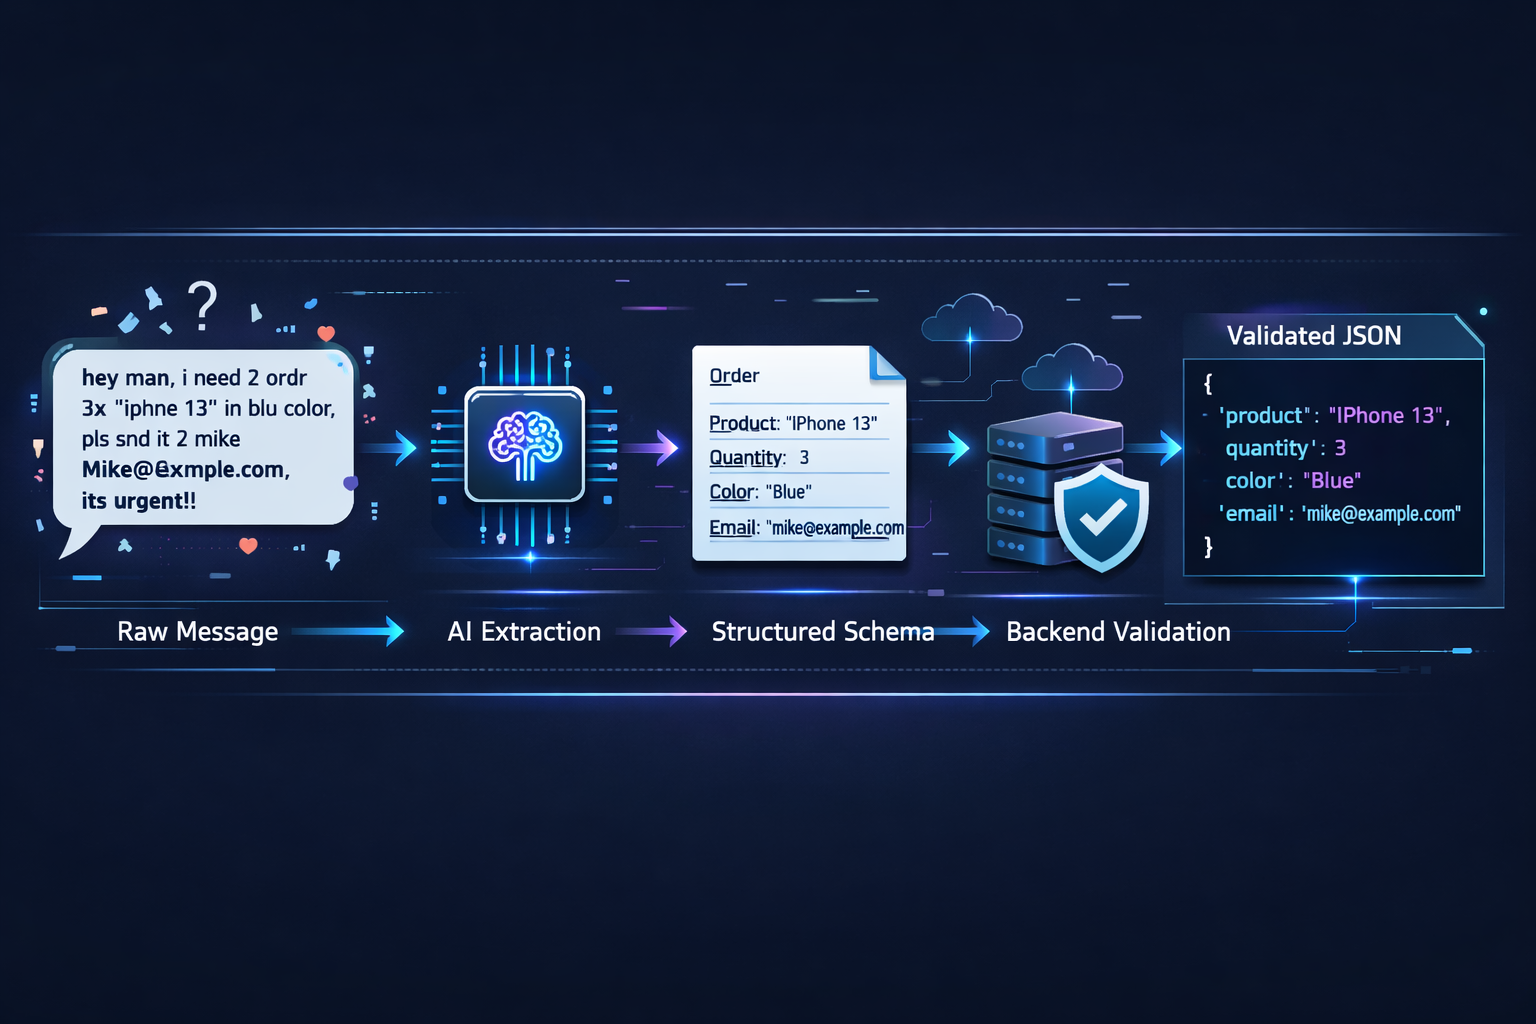
Your users send messy text. Your backend expects clean JSON. Here's how to bridge that gap reliably with a single LLM call.

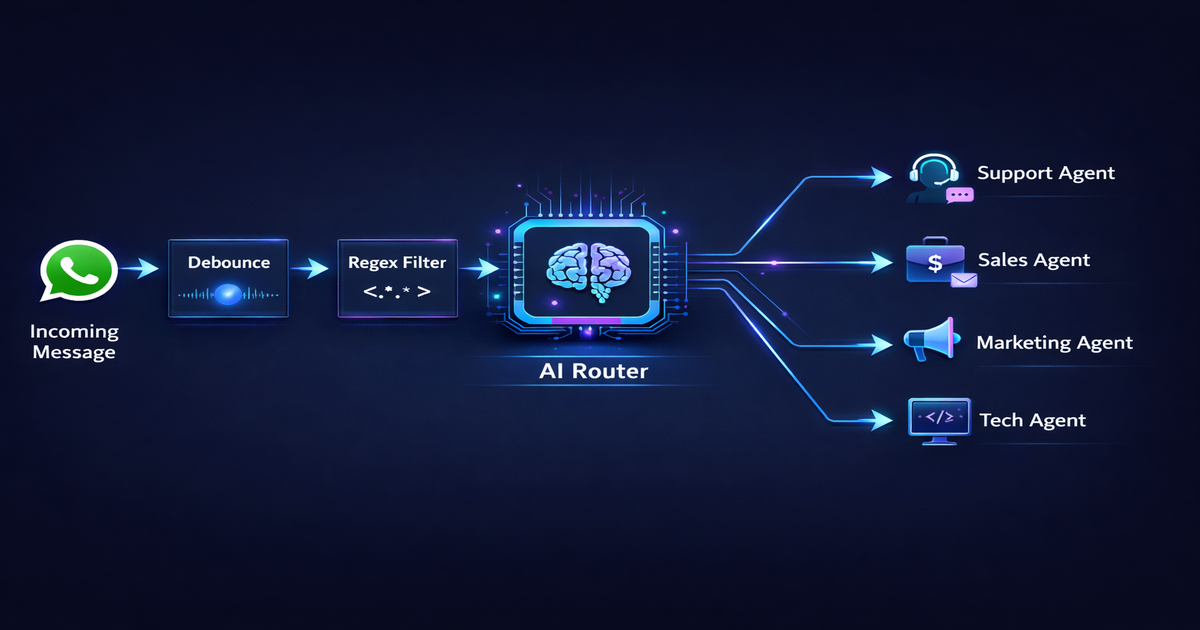
Most teams run every message through every agent. We built a pipeline that filters 65% of noise for free and routes with a single LLM call.

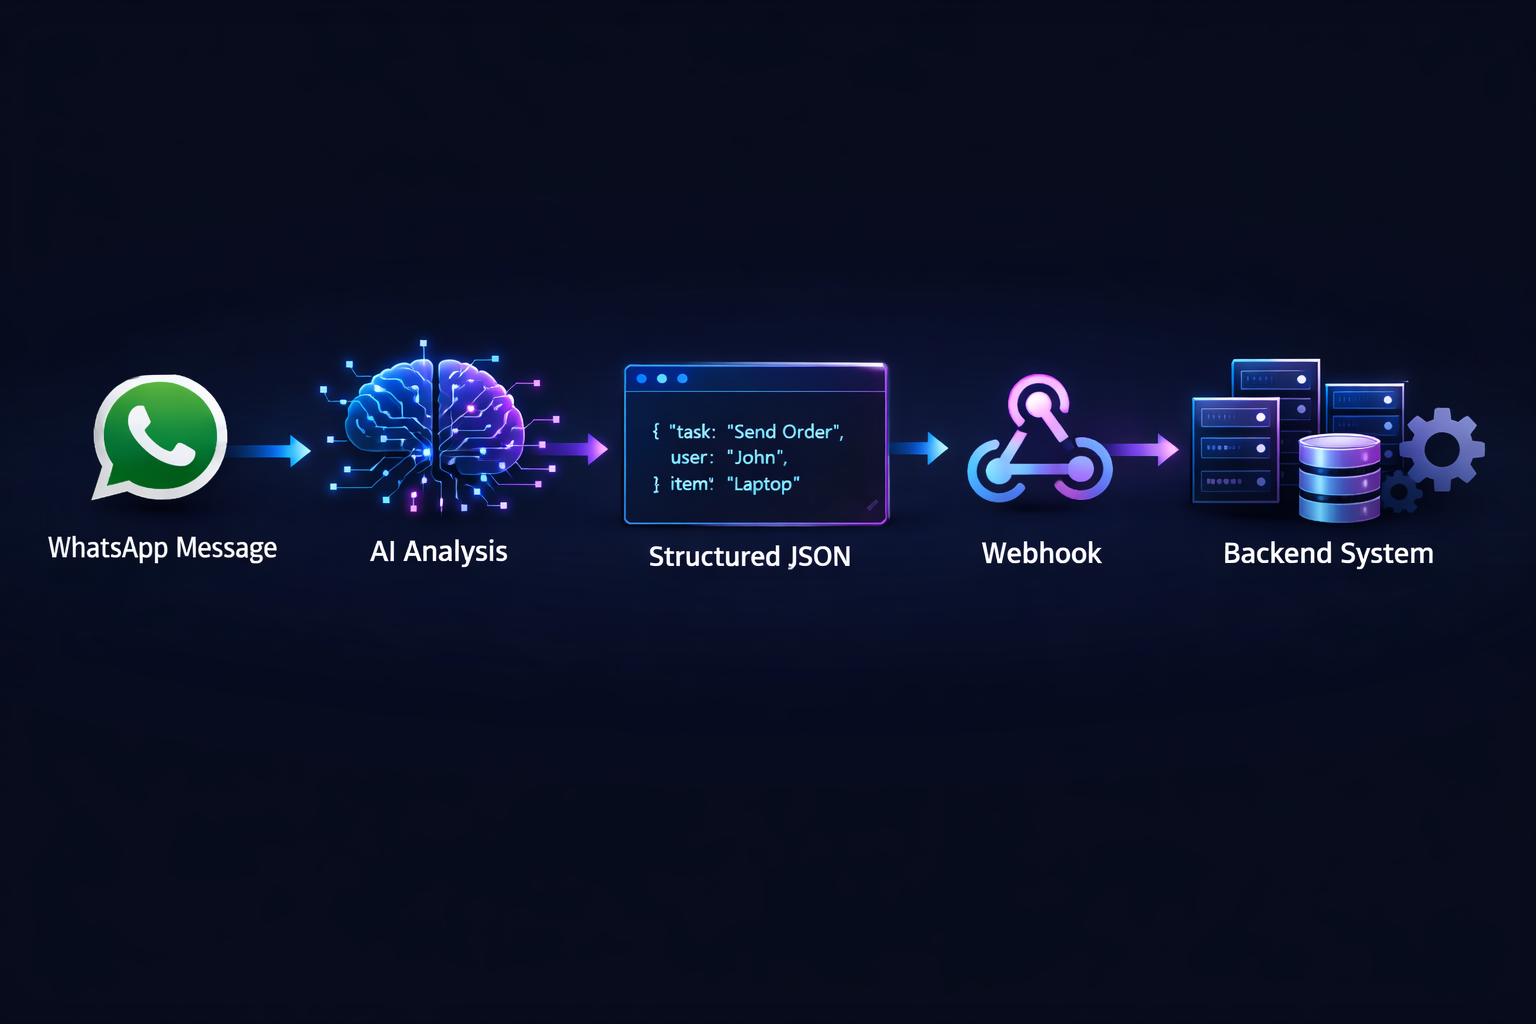
Most teams building on WhatsApp are building chatbots. But most of them don't actually need a chatbot — they need a system that turns incoming messages into backend actions.